The story behind this piece
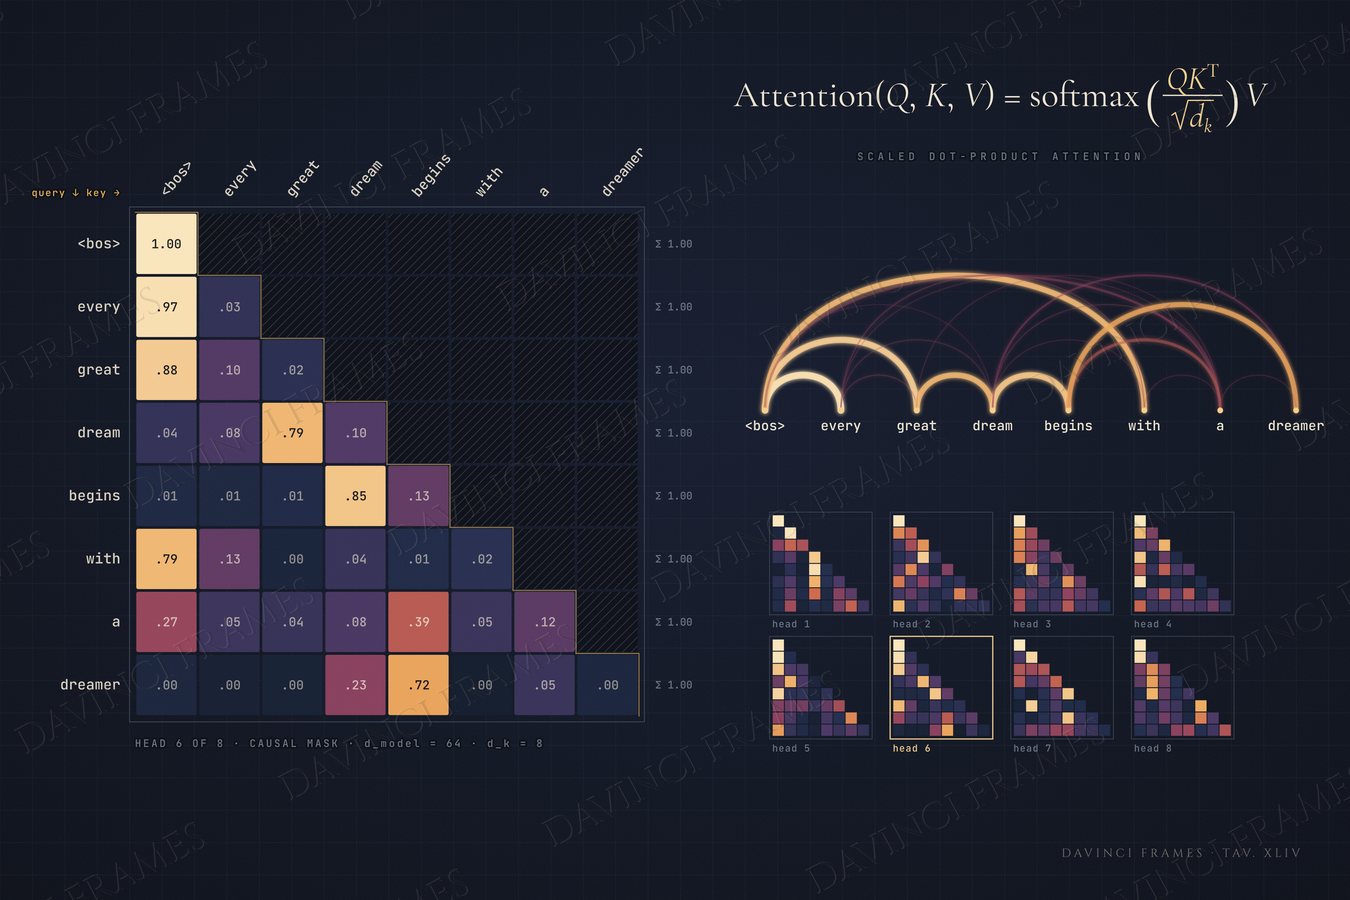
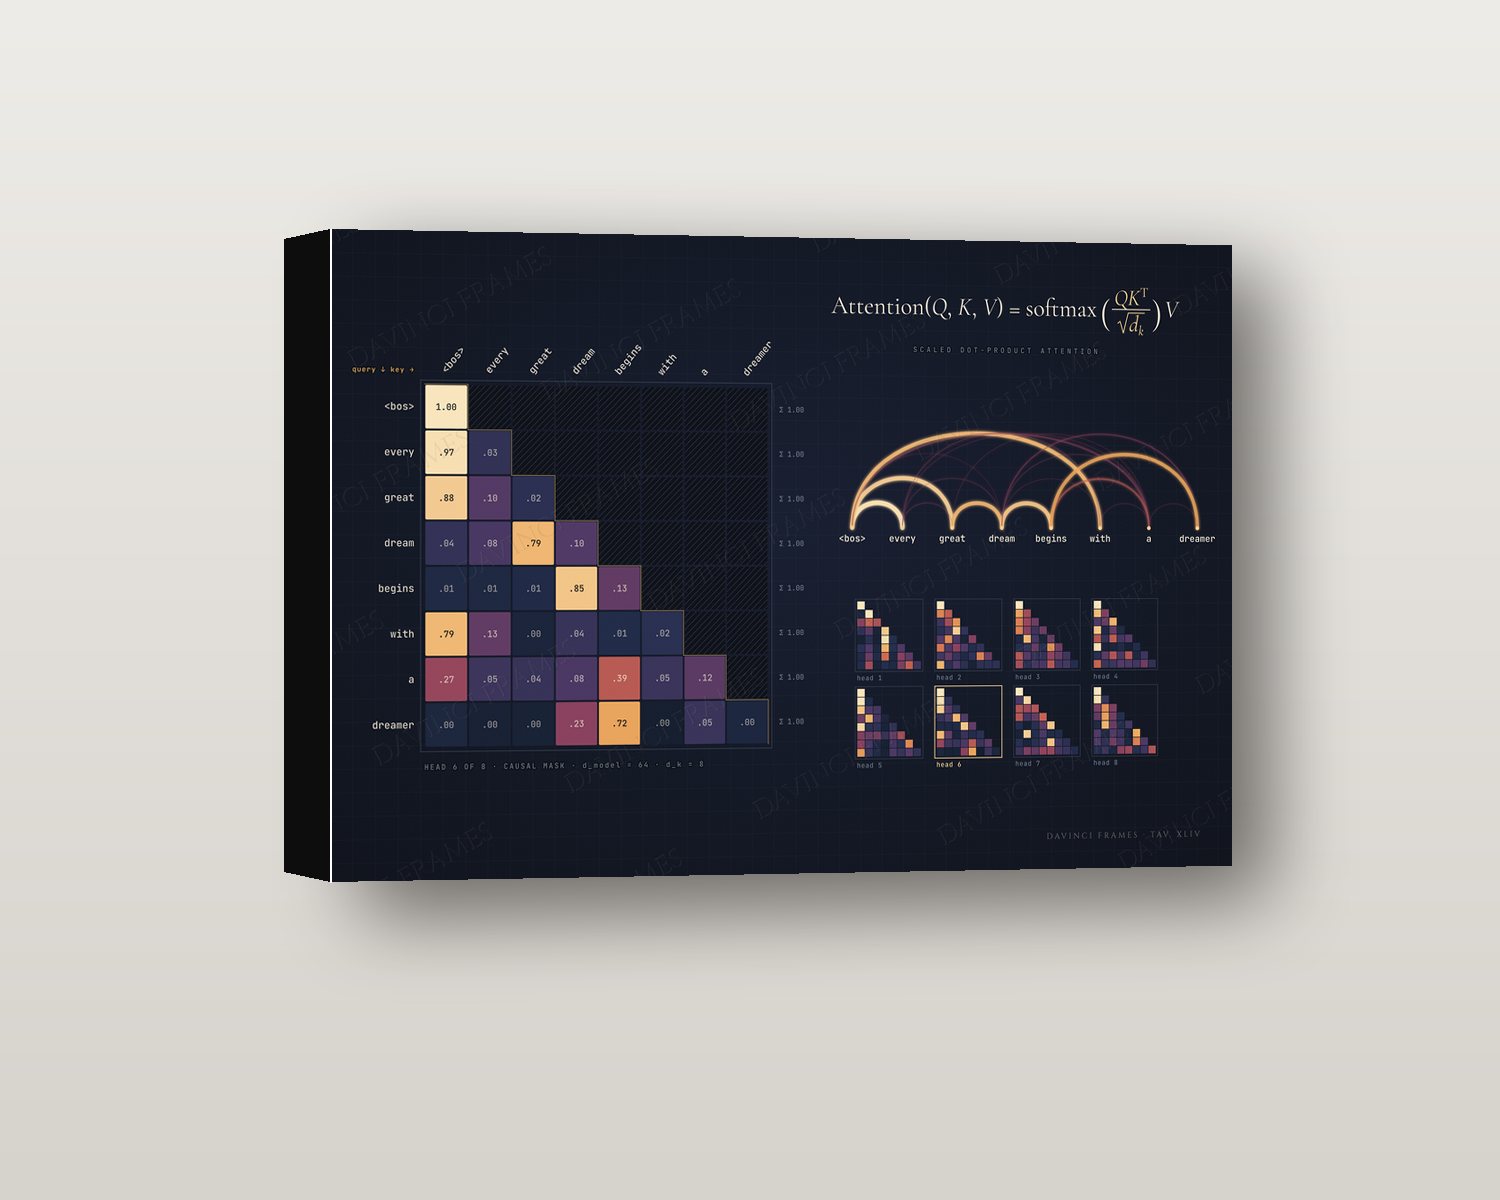
Attenzione shows the one equation inside every transformer. The sentence "every great dream begins with a dreamer" is split into tokens after a <bos> start marker. Each token becomes a 64-dimensional embedding plus a sinusoidal position code. Eight heads project these into queries and keys with d_k = 8, and the weights are computed exactly as softmax(QKᵀ/√d_k). A causal mask hides future words, which is the hatched triangle, so every row is a probability distribution that sums to one. The large matrix is the sharpest head. Arcs show the same weights as reach back along the sentence, and all eight heads appear as small multiples. The projections are random, not trained, so the patterns are honest arithmetic rather than learned meaning.